PrismML, a burgeoning artificial intelligence laboratory, is rapidly gaining prominence within the tech landscape, not merely for its foundational $22.25 million seed funding from strategic investors like Khosla Ventures, Cerberus Capital, and Caltech, but for its profound technical ingenuity and the potentially transformative impact of its innovations on the AI industry. At its core, PrismML challenges the prevailing notion that highly capable, reasoning large language models (LLMs) must inherently be gargantuan in size, instead demonstrating that powerful AI can be dramatically miniaturized to operate efficiently on consumer-grade devices.
The Dawn of Compact AI: PrismML’s Breakthrough in On-Device Intelligence
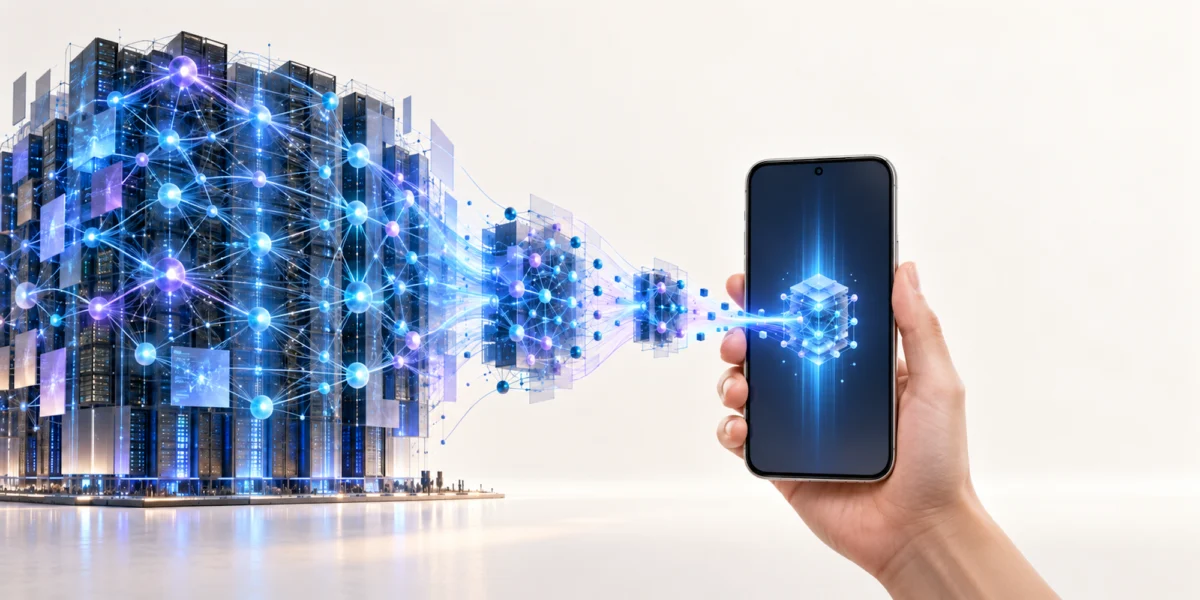
In an era defined by the exponential growth of artificial intelligence, particularly large language models, the computational demands have escalated dramatically. Models like OpenAI’s GPT series, Google’s Gemini, and Meta’s LLaMA have pushed the boundaries of what AI can achieve, but often at the cost of immense processing power, vast memory requirements, and significant energy consumption. These resource-intensive models primarily reside in the cloud, necessitating constant internet connectivity and raising concerns about data privacy, latency, and operational costs. PrismML directly addresses this critical bottleneck, asserting that sophisticated reasoning capabilities can be distilled into a fraction of their original size, making them accessible and deployable on personal computers and even high-end smartphones. This vision promises to democratize advanced AI, moving it from centralized data centers to the fingertips of billions.
The company recently marked a significant milestone with the release of Bonsai 2 27B, the latest iteration in its family of compact AI models. This model showcases an astonishing feat of engineering: compressing Alibaba’s Qwen3.8 27B, a widely adopted open-source model known for its robust performance, from an estimated original size of approximately 59 GB down to a mere 5.9 GB. This represents a staggering 9x to 10x reduction in memory footprint, rendering the model perfectly suitable for deployment on contemporary PCs and, critically, on advanced smartphones. The ability to run such a powerful model locally on a device opens up unprecedented possibilities for real-time applications, enhanced privacy, and reduced reliance on cloud infrastructure. This technical achievement has not gone unnoticed, with industry whispers suggesting that PrismML is already in discussions with tech giants like Apple regarding potential integration into devices such as the iPhone, though CEO Babak Hassibi has refrained from commenting on these specific rumors.
The Architects of Efficiency: Leadership, Expertise, and Strategic Backing
PrismML’s formidable technical prowess is rooted in its distinguished founding team, a collective of brilliant researchers from the California Institute of Technology (Caltech). The startup is spearheaded by Babak Hassibi, a renowned Caltech professor and a leading authority in the intricate field of compression technologies. Hassibi’s extensive background in signal processing, information theory, and machine learning provides the bedrock for PrismML’s innovative approach to AI miniaturization. His deep academic and research insights are pivotal in developing algorithms that can drastically reduce model sizes while preserving, and in some cases enhancing, their core intelligence.
Further solidifying PrismML’s strategic direction and technical credibility is the involvement of Ion Stoica as an advisor. Stoica is a towering figure in the computing world, celebrated as a co-founder of Databricks, a data and AI company valued in the tens of billions, and several other successful ventures. He also directs the esteemed Sky Computing Lab at the University of California, Berkeley, an incubator renowned for birthing groundbreaking technologies and successful startups, including cutting-edge AI firms like Letta and SGLang. Stoica’s extensive experience in scaling innovative technologies from research labs to commercial success, coupled with his profound understanding of distributed systems and cloud computing, offers invaluable guidance to PrismML as it navigates the complex landscape of AI deployment and market adoption. His involvement underscores the profound potential seen in PrismML’s technology by some of the industry’s most discerning minds.
The investor syndicate backing PrismML further highlights its strategic positioning. Khosla Ventures, a venture capital firm with a storied history of investing in disruptive deep tech and AI companies, signals strong confidence in PrismML’s long-term vision. Cerberus Capital, typically known for its focus on distressed investing and private equity, brings a different dimension of financial backing and operational expertise, suggesting a robust foundation for scaling the company. The participation of Caltech itself, through its investment vehicles, not only provides financial support but also reinforces the academic rigor and scientific validation behind PrismML’s core innovations, fostering a symbiotic relationship between cutting-edge research and commercial application.
Performance Beyond Size: Benchmarks and Real-World Impact
A critical differentiator for PrismML in the competitive landscape of LLM compression is its unwavering commitment to maintaining, and even enhancing, model performance. While various techniques exist to reduce the size of AI models, they often come at the expense of accuracy and reasoning capabilities. Hassibi emphatically states that PrismML’s compression technology ensures virtually no degradation in performance compared to the original, uncompressed models. This claim is substantiated by the performance of Bonsai 2, which matches an impressive 98% of Qwen’s aggregate benchmark scores. This represents a notable improvement from the first iteration of Bonsai, released just a few months prior in March, which achieved 95% parity.
The rapid adoption of PrismML’s models further validates their effectiveness. The original Bonsai model has already garnered over 11 million downloads, with PrismML’s even smaller models collectively downloaded an additional 2.6 million times. These figures unequivocally demonstrate a substantial market demand for efficient, high-performing compact LLMs and underscore the trust developers and users are placing in PrismML’s technology.
While the pursuit of 100% benchmark performance parity remains a theoretical ideal, Hassibi pragmatically acknowledges that some marginal impact from compression is almost inevitable. However, he also points out that perfect benchmark parity is often an academic rather than a practical concern. Large language models, even in their uncompressed forms, are not infallible, and benchmarks themselves are not always perfectly reflective of real-world task performance. A 2% degradation in aggregate benchmark scores is unlikely to meaningfully affect how a model performs in actual use cases. Furthermore, the overall "harness" or surrounding software environment in which a model operates plays a significant role in its accuracy and efficacy. Optimized inference engines, sophisticated prompt engineering, and robust system integrations can often compensate for minor theoretical performance differences, ensuring a seamless and effective user experience. This holistic view emphasizes that true AI utility extends beyond raw model parameters.
The Ingenuity of Ternary Weights: A Technical Deep Dive
The core of PrismML’s breakthrough lies in its proprietary compression technique, which focuses on shrinking the "weights" that constitute an AI model. In essence, these weights represent the vast array of information, patterns, and relationships a model learns and stores during its intensive training phase. Traditionally, each of these weights requires 16 bits of data to store, leading to the massive file sizes characteristic of modern LLMs.
PrismML’s innovative approach, termed "ternary weights," dramatically simplifies this storage requirement. Instead of 16 bits, each weight is reduced to one of only three possible values: +1, -1, or 0. This radical simplification means that far less data needs to be stored for each individual weight, resulting in a monumental reduction in the model’s overall memory footprint. This method is distinct from other common quantization techniques, such as 8-bit or 4-bit quantization, which merely reduce the precision of the numerical values. Ternary weights fundamentally re-architect the representation of information within the neural network, allowing for extreme compression while rigorously preserving the model’s learned intelligence. This innovative approach is a testament to the deep theoretical understanding and engineering excellence of the PrismML team, with further technical details available on the project’s GitHub page.
The Competitive Landscape and Market Dynamics of LLM Compression
PrismML operates within an increasingly dynamic and competitive sector focused on LLM compression. The industry has recognized the immense value in making AI more accessible and efficient, leading to various research and commercial efforts in this domain. Companies and research institutions are exploring a range of techniques, including pruning (removing less important connections), knowledge distillation (training a smaller "student" model to mimic a larger "teacher" model), and different forms of quantization.
One notable competitor is Multiverse Computing, a company founded by a distinguished professor from Spain’s Donostia International Physics Center. Multiverse Computing has also made significant strides in compressed AI models and, importantly, has attracted substantial investment, indicating the broad industry recognition of this critical technological frontier. Other players, from tech giants like Google (with its Gemma models optimized for on-device use) and Meta (with initiatives like Llama.cpp), to various startups and open-source communities, are all vying to make AI more compact and efficient.
What sets PrismML apart is its demonstrated ability to achieve aggressive compression ratios (9x-10x) while consistently maintaining exceptionally high performance parity (98%). This combination is a powerful differentiator in a market where compromises between size and capability are often necessary. The race for efficient, on-device AI is driven by several compelling factors: enhanced privacy by keeping data local, reduced latency for real-time applications, lower operational costs by minimizing cloud dependency, and improved energy efficiency, which is crucial for sustainable AI development.
Future Horizons: Scaling Up and Democratizing Advanced AI
Looking ahead, PrismML’s next ambitious goal is to extend its groundbreaking compression technique to even larger and more complex models. Hassibi revealed that the company anticipates releasing models in the "several-hundred-billion-parameter range" within the next couple of months. This is a crucial strategic move, as these models approach or even surpass the scale of some of the most advanced proprietary LLMs currently available.
Intriguingly, Hassibi suggests that compressing these significantly larger models might actually be "easier to retain the intelligence there." This counter-intuitive statement can be understood in the context of over-parameterization in modern LLMs. Many state-of-the-art models are trained with far more parameters than strictly necessary, leading to inherent redundancies. These redundancies create "more room" for intelligent compression without sacrificing core capabilities. As Hassibi explains, "for larger models, it’s easier to get to 100%" benchmark parity, implying that the additional complexity and redundancy provide a richer substrate for the ternary weight approach to identify and preserve essential information while discarding non-critical components.
Ion Stoica, echoing the profound implications of PrismML’s work, articulates a transformative vision for the future of AI. He emphasizes that this technology is making it possible for advanced models to run directly on users’ devices, ushering in an era where "intelligence at your fingertips" becomes a reality. This paradigm shift offers multifaceted benefits:
- Privacy: By processing data locally, sensitive information never leaves the user’s device, eliminating the need to transmit data to cloud servers. This is a game-changer for applications involving personal health records, financial data, confidential communications, and other privacy-sensitive domains.
- Accessibility and Cost-Efficiency: On-device AI effectively makes advanced intelligence "free" in the sense that it leverages hardware users have already purchased. It drastically reduces reliance on expensive cloud GPU infrastructure for inference, lowering operational costs for businesses and democratizing access to powerful AI for individuals, especially in regions with limited internet connectivity or economic resources.
- Low Latency and Real-time Processing: Without the need for network roundtrips to the cloud, on-device models can deliver instantaneous responses, enabling real-time interactions for applications like voice assistants, augmented reality, and autonomous systems.
- Energy Efficiency: While running locally, these highly compressed models can consume significantly less power than continuously streaming data to and from energy-intensive cloud data centers, contributing to a more sustainable AI ecosystem.
Broader Implications and Industry Impact
The success of PrismML’s compression technology carries far-reaching implications across various industries and technological domains. For hardware manufacturers like Apple, Qualcomm, and Samsung, the ability to run advanced LLMs efficiently on their devices is a massive competitive advantage. It means new functionalities can be unlocked on existing or slightly upgraded hardware, extending product lifecycles and enhancing user experiences without demanding constant network access.
New application paradigms will undoubtedly emerge. On smartphones, this could mean hyper-personalized AI assistants that understand context deeply, real-time language translation without latency, advanced creative tools for content generation, and sophisticated on-device image and video processing. For personal computers, local coding assistants, advanced document summarization and analysis, and high-fidelity creative content generation tools become feasible without relying on subscription services or internet access. Beyond consumer devices, the impact on edge computing—including robotics, Internet of Things (IoT) devices, automotive AI, and industrial automation—is profound. It enables sophisticated reasoning capabilities to be deployed in environments with stringent power, connectivity, and latency constraints, driving innovation in autonomous systems and smart infrastructure.
While the benefits are substantial, the democratization of powerful AI also brings ethical considerations. Ensuring the safety, alignment, and responsible use of highly capable models running on individual devices will be paramount. Mechanisms for updates, model oversight, and preventing misuse will need to be carefully considered and integrated into the ecosystem.
PrismML stands at the vanguard of a movement to redefine the landscape of artificial intelligence. By proving that powerful LLMs need not be large, the company is not just optimizing technology; it is laying the groundwork for a future where advanced AI is ubiquitous, private, and seamlessly integrated into our daily lives, transforming how we interact with technology and the world around us. Its blend of deep scientific innovation, strategic leadership, and strong financial backing positions it as a pivotal player in shaping the next chapter of AI development.
About the Author